Table of Contents
Claude Code vs Cursor vs OpenCode: the Q4 2026 buy decision
Three months ago this was a two-tool question. It is not anymore. Since the July head-to-head on this site, SpaceX closed its $60 billion purchase of Cursor on August 14, OpenAI set a November 12 shutoff for its models running inside Cursor, and Claude Code climbed to the top spot in LogRocket's September dev-tool rankings while OpenCode, MIT-licensed and model-agnostic, settled in right behind it at #2, per LogRocket. Short version: Claude Code for the solo dev who wants the best score on the page, OpenCode for anyone who wants the vendor-lock question to disappear, and Cursor if the full IDE is the reason you showed up and you are fine staying month to month through the November deadline.
The specs, side by side
| Tool | Price/mo | Models after Nov 12 | License | Interface | Cloud agents |
|---|---|---|---|---|---|
| Claude Code | $20 Pro to $200 Max (Anthropic) | Fable 5.1, Opus 5, Sonnet 5 | Closed | Terminal, IDE, web, CI | Yes, async runs |
| Cursor | Free; $20 Pro; $40/seat Teams (Cursor) | Loses OpenAI models; keeps Claude, Gemini, Grok 4.6 (OpenAI) | Closed | Full IDE | Yes, Projects subagents |
| OpenCode | $0 plus your API usage (OpenCode) | Any of 75+ providers you bring | MIT (open) | Terminal (CLI) | No built-in cloud |
Every one of these sits at the low end of the market, so price is not what separates them. The model roster, the license, and who owns the pipe your code runs through are.
Claude Code: the quality-first pick
Claude Code is Anthropic's agent that drives your repo from the terminal, and as of this quarter it also runs from an IDE, the web, and CI through GitHub. You hand it a task, it reads files, edits, runs tests, and loops until the work is done. One session, one thread, synchronous. That shape has not changed since July. What changed is how good the model underneath it got.
It rose from #2 to #1 in LogRocket's September rankings, and the reason is the model it now runs. Claude Fable 5.1 posts 1762 Elo on the WebDev Arena leaderboard, 73 points clear of Fable 5 and the highest score of any model inside any tool LogRocket measured, per LogRocket. Cache reads dropped 75% to $0.25 per million tokens, which trims real agentic cost by roughly a quarter on typical work and up to 45% on heavy agent runs, per the same ranking. In blind reviews LogRocket cites, Claude Code output was preferred 67% of the time against Codex's 25%. If your buying criterion is the best answer on a hard change, this is the tool with the best answer.
The main drawback is price: there is no free tier. Claude Code rides on a paid Claude plan, $20 a month for Pro at the low end and $200 for Max, billed monthly, per Anthropic. A hobbyist who wants to poke at an agent for free cannot start here.
Where it fits: a developer or team that values model quality over IDE polish and lives comfortably in a terminal. The candid con is the single-session shape. Claude Code does one body of work at a time in a thread you are watching, so if your workload is dozens of parallel tasks running while you sleep, you are fighting the tool instead of using it. For deep, correct, one-thing-at-a-time work, nothing here beats it.
Cursor: the full-IDE pick, now with a governance asterisk
Cursor is still the most complete editor experience of the three, and that has not slipped. It holds #3 in the September rankings on the strength of the full IDE, with Grok 4.6 now live across all plans, per LogRocket. The September 10 launch of Projects is the real new capability: a coordinator agent sits over a whole feature or migration, delegates to thousands of cloud subagents, keeps context across months, and acts on Slack messages or PRs without being prompted. Cursor's own numbers put new users at 30% more merged PRs and heavy Projects users at six times as many, per Cursor. Read those as vendor figures, but the work pattern is genuinely different from a single agent loop.
Ownership is the open risk with Cursor. SpaceX closed its $60 billion acquisition on August 14, folding Cursor into the SpaceXAI division while the legal entity stays Anysphere, per The Next Web and TechCrunch. Cursor's pitch for the deal is compute: access to what it calls the largest fleet of GPUs in the world, and cheaper models as a result. The cost showed up fast. OpenAI said on August 28 it will wind down the contract that provides its models to Cursor, with a shutoff date of November 12, citing a change-of-control clause and its own history of Musk-owned companies breaking contract terms, per OpenAI. One major model supplier has already walked. After November 12, Cursor keeps Claude, Gemini, and Grok, and loses GPT.
Pricing is the most forgiving of the three at the low end: a free Hobby tier with no card required, $20 a month for Pro, and $40 per seat for Teams, which adds team-wide privacy mode and SAML/OIDC SSO, per Cursor. Enterprise pricing is quote-based.
Where it fits: a developer whose productivity is tied to a real editor with inline diffs, and a team that wants long-horizon parallel work through Projects. The candid con is not a feature gap, it is supplier risk. Your code now flows through SpaceX infrastructure, and one vendor citing trust concerns invites the question of whether a second follows in Q1 2027. LogRocket flags the market reading it the same way: Cursor's share on Ramp's corporate-spend data slid from 41% to 26%.
OpenCode: the no-lock-in pick
OpenCode is the terminal agent most readers have not evaluated, because it has no marketing budget and an MIT license instead. It routes to more than 75 model providers, integrates the language server for real symbol awareness, and runs fully air-gapped if you need it to, per LogRocket. You bring the model; OpenCode is the harness around it.
It dropped from #1 to #2 this quarter, and the reason matters for the buy decision. LogRocket is explicit that the slip reflects Claude Code's widening quality lead, not any regression in OpenCode, which now serves Fable 5.1, Opus 5, and Kimi K3 among its providers. In other words, you can point OpenCode at the same 1762-Elo Fable 5.1 that put Claude Code at #1, and you are not paying a subscription for the privilege.
The main reason to pick OpenCode is cost. OpenCode itself is free. You pay only for the API tokens you burn, or nothing at all if you route to a free-tier model, per OpenCode's docs. For a solo dev already holding an Anthropic or OpenAI key, the monthly bill can be lower than either subscription. For a team with data-residency rules, the air-gapped, self-hosted option removes the entire question of whose cloud your code sits in.
Where it fits: anyone who wants zero vendor lock and control over which model and which provider handles their code. The candid con is that there is no built-in cloud execution. OpenCode runs where your terminal runs, so the async, close-your-laptop, thousands-of-subagents pattern that Cursor Projects sells is not on the menu. You also own the setup: keys, provider config, and cost tracking are yours to manage.
New research: harness overhead usually decides the cost gap, not the model
Two studies published in October 2026 put a number on a question this guide has only argued by anecdote until now: how much of a Claude Code or OpenCode bill is the model, and how much is the wrapper around it.
Researchers at Shandong University ran five open-weight and API-served models through three production harnesses, Claude Code, OpenCode, and the minimal research harness mini-SWE-agent, on nearly 500 SWE-bench Verified tasks, plus Claude Opus 5 inside Claude Code as a top-tier anchor. On the larger 447-task pool, Claude Code and mini-SWE-agent, the heaviest and lightest of the three, scored within two percentage points of each other, per the arXiv paper. Cost did not stay close. "With the same model, the same tasks, and one price list, cost per task differs by up to 3x across harnesses," the researchers write, and on GLM-5.3-Flash a trial in Claude Code cost nearly twice as much as a trial in mini-SWE-agent and more than three times as much as a trial in OpenCode, per VentureBeat's report on the study.
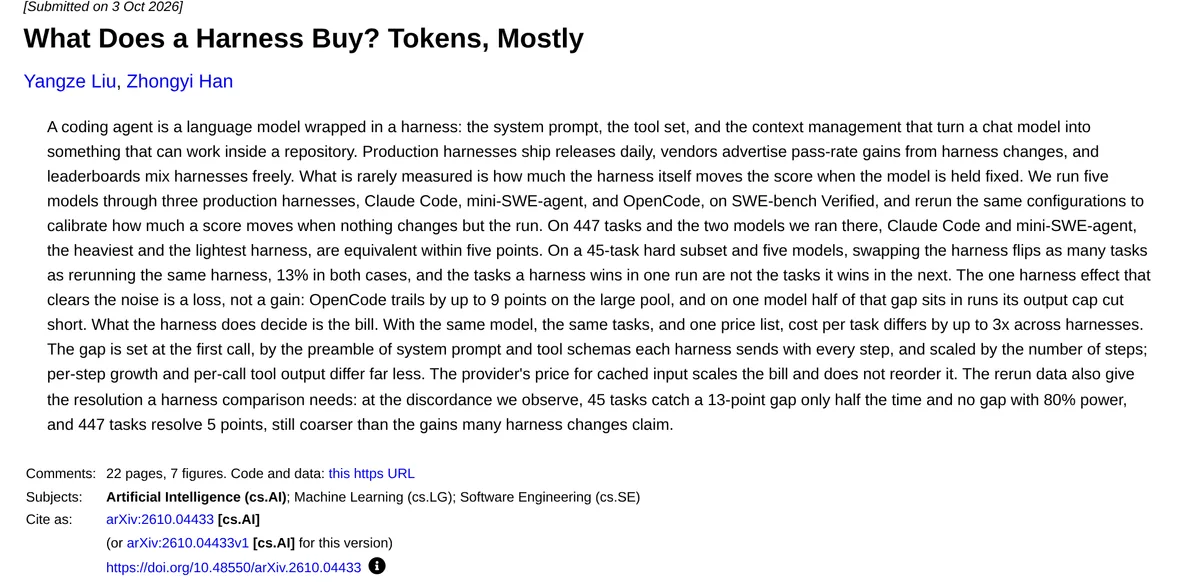 Source: arxiv.org, captured October 24, 2026.
The gap starts at the first API call. Every step, each harness resends its own system prompt and tool schemas, and that preamble multiplies by however many steps a task takes. Per the researchers' token counts, cited by VentureBeat, the first call carried 16,581 tokens in Claude Code, 7,025 in OpenCode, and 829 in mini-SWE-agent, smallest of the three. Smallest preamble did not mean cheapest run, though: on GLM-5.3-Flash, OpenCode finished as the cheapest harness overall because it also needed fewer model calls per task, which outweighed mini-SWE-agent's lighter starting context. Multi-step cost is preamble size times call count, and the two studies found that harnesses differ on both.
| Harness | Initial context (tokens) | Cost on GLM-5.3-Flash |
|---|---|---|
| Claude Code | 16,581 | Highest of the three |
| OpenCode | 7,025 | Lowest, fewer model calls offset the larger preamble |
| mini-SWE-agent (research harness, not a commercial product) | 829 | Middle, despite the smallest preamble |
Source: arXiv 2610.04433; multipliers per VentureBeat, Oct 23, 2026.
The ranking is not fixed across models. On DeepSeek-V4-Flash in the same study, mini-SWE-agent took more model calls than Claude Code and ended up costing slightly more per trial, about 15.2 cents against 14.6 cents, per VentureBeat. Treat the GLM result as one data point, not a universal law.
This corroborates an earlier study. UC Berkeley's Sky Computing Lab and the Arena team ran seven models through Claude Code, OpenAI's Codex CLI, and Pi, a four-tool open-source harness, across SWE-bench Lite and Terminal-Bench 2.0. The cost gap held across shared models: about 2.0 times as much as Pi and 1.6 times as much as Codex on SWE-bench Lite, and 1.5 times as much as Pi on Terminal-Bench 2.0, using geometric means of cost ratios, while success rates moved by roughly 2 percentage points on one benchmark and 5 on the other, per Arena's HarnessTax writeup. Its mean initial context across the seven models ran more than ten times Pi's. Claude Fable 5 solved 97.8% of attempts inside Claude Code against 96.7% inside Pi, at close to double the cost per rollout, $1.33 against $0.67, per the same writeup.
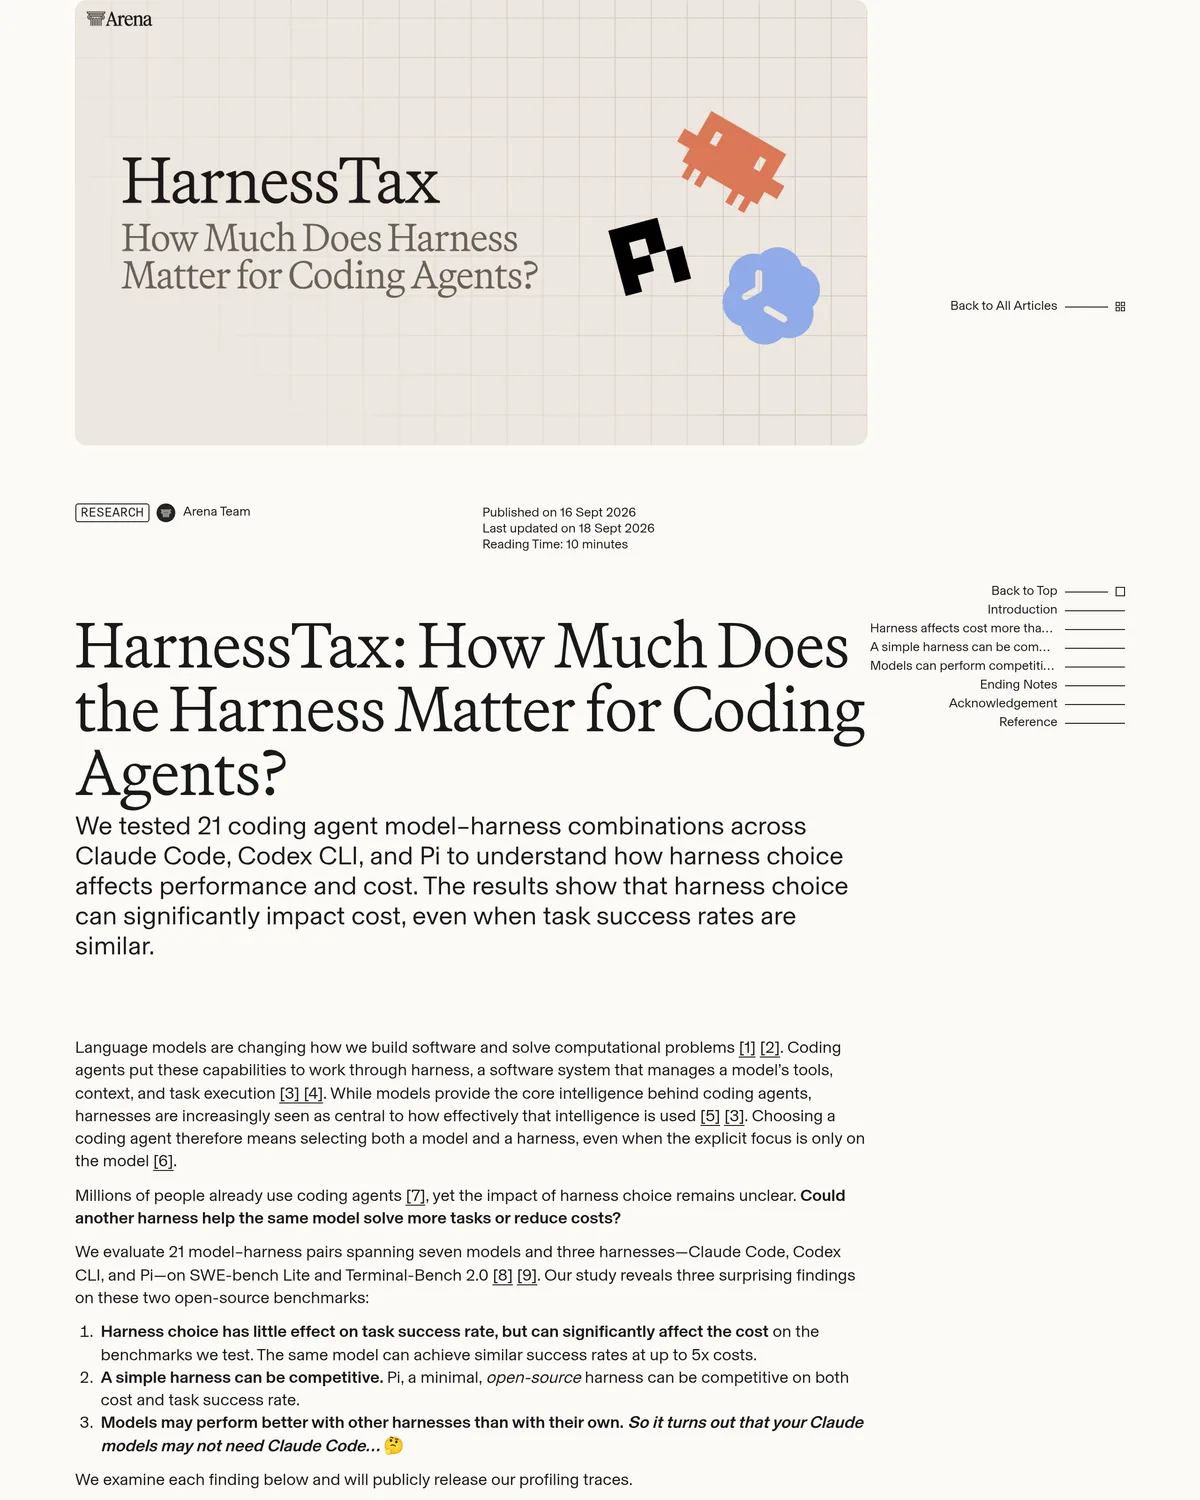 Source: arena.ai, captured October 24, 2026.
Read both studies for what they measured. This is a cost finding, not an accuracy one. Neither paper found Claude Code's harness produces worse code; on the hardest task subset in the Shandong study, swapping harnesses flipped about as many results, 13% at the median, as simply rerunning the same harness unchanged, per VentureBeat. What the data settles is narrower: a meaningful share of Claude Code's bill is its own preamble, resent on every turn, independent of which model answers.
For the buy decision in this guide, that adds evidence to the OpenCode pick without rewriting it. OpenCode was already the cost play because there is no subscription fee; this is data that its per-step overhead can run lighter too, at least on the model and workload both studies tested. It is not a rule to bank on for every model, the DeepSeek result above argues against that, so the honest move is to price your actual task against your actual harness rather than trust a per-token rate card. None of it touches the Claude Code pick on raw output quality: neither study measured anything beyond pass or fail on a benchmark suite, and Claude Code's edge in this guide rests on LogRocket's broader ranking, not on these two cost papers.
Setting them up, and what a run looks like
Two of the three install from a terminal in one line. Claude Code rides on npm:
# Install Claude Code and start a session in your repo
npm install -g @anthropic-ai/claude-code
cd your-project
claude
OpenCode installs from its own script or a package manager, then you point it at a provider with an environment variable:
# Install OpenCode (or: npm i -g opencode-ai)
curl -fsSL https://opencode.ai/install | bash

# Bring your own key, then launch in the repo
export ANTHROPIC_API_KEY=<YOUR_KEY>
cd your-project
opencode
Cursor is the outlier here: it is a downloaded IDE, not a CLI, so setup is install the app, open your folder, and sign in. Two of these are terminal agents you can drop into CI or a remote box; one is an editor you sit inside.
A task run looks similar across the two CLIs. You describe the change, the agent reads context, edits, and reports back. The shape of a terminal session, per each tool's docs:
> add a rate limiter to the /api/upload route, 10 requests per minute per IP

  Reading  src/routes/upload.ts
  Reading  src/middleware/index.ts
  Editing  src/middleware/rate-limit.ts   (+34)
  Editing  src/routes/upload.ts           (+3)
  Running  npm test upload
  Passed   12 tests
# ... (agent summarizes the diff and the files it touched)
The output you care about is the diff and the test result, not the token count. That is the same loop Claude Code and OpenCode both run; the difference is the model behind it and who bills you for the tokens.
Which one for your situation
| Your situation | The pick | Why |
|---|---|---|
| Solo dev on a budget | OpenCode | Free harness, pay only for tokens, or route to a free-tier model and pay nothing |
| Solo dev who wants the best SWE score | Claude Code | Runs Fable 5.1 at 1762 Elo, the top model score in any tool (LogRocket) |
| Small team, 3 to 10 seats | Cursor Teams, month to month | $40/seat, privacy mode and SSO, Projects for parallel work; skip the annual term until after Nov 12 |
| Team with data-residency rules | OpenCode | MIT, air-gapped, self-hosted; your code never leaves your infrastructure |
| Enterprise signing an annual contract | Claude Code or OpenCode | Avoid locking a multi-year term to a supplier whose model roster just lost OpenAI |
The verdict
For the solo developer, the split comes down to budget versus ceiling. If you want the strongest result on a hard change and can spend $20 a month, start with Claude Code on the Pro plan (Anthropic); it runs the highest-scoring model in the category and you feel it on complex edits. If you would rather not pay a subscription at all, install OpenCode, bring your existing API key, and point it at Fable 5.1 or a free-tier model. Skip Cursor Pro as your primary unless the editor itself is the reason you code faster.
For the small team of three to ten, buy Cursor Teams at $40 a seat (Cursor) for the editor and Projects, but keep it month to month and do not sign the annual term before the November 12 OpenAI shutoff passes. Run Claude Code alongside it for whoever needs the top model on deep work, and re-price the whole stack in January once you can see which suppliers actually remain in Cursor's roster.
For the enterprise about to sign a multi-year contract, do not put the annual commitment on Cursor this quarter. One supplier already invoked a change-of-control clause and walked, and a second departure in Q1 2027 is a live risk you would be underwriting. Standardize on Claude Code for governed model quality, or OpenCode if data residency or air-gapping is a hard requirement, and revisit Cursor for an annual deal only after it publishes a written commitment on its remaining model supply.
What changed
This guide is updated in place as the facts change. Earlier version:
- October 24, 2026: Added the Shandong University (October 2026) and UC Berkeley "HarnessTax" (September 2026) cost-overhead studies, which measure how much of a coding agent's bill comes from the harness itself rather than the model. This is a cost finding, not an accuracy one. Success rates stayed within a few percentage points across harnesses in both studies (current version).
- September 22, 2026: Claude Code vs Cursor vs OpenCode: the Q4 2026 buy decision